Problem
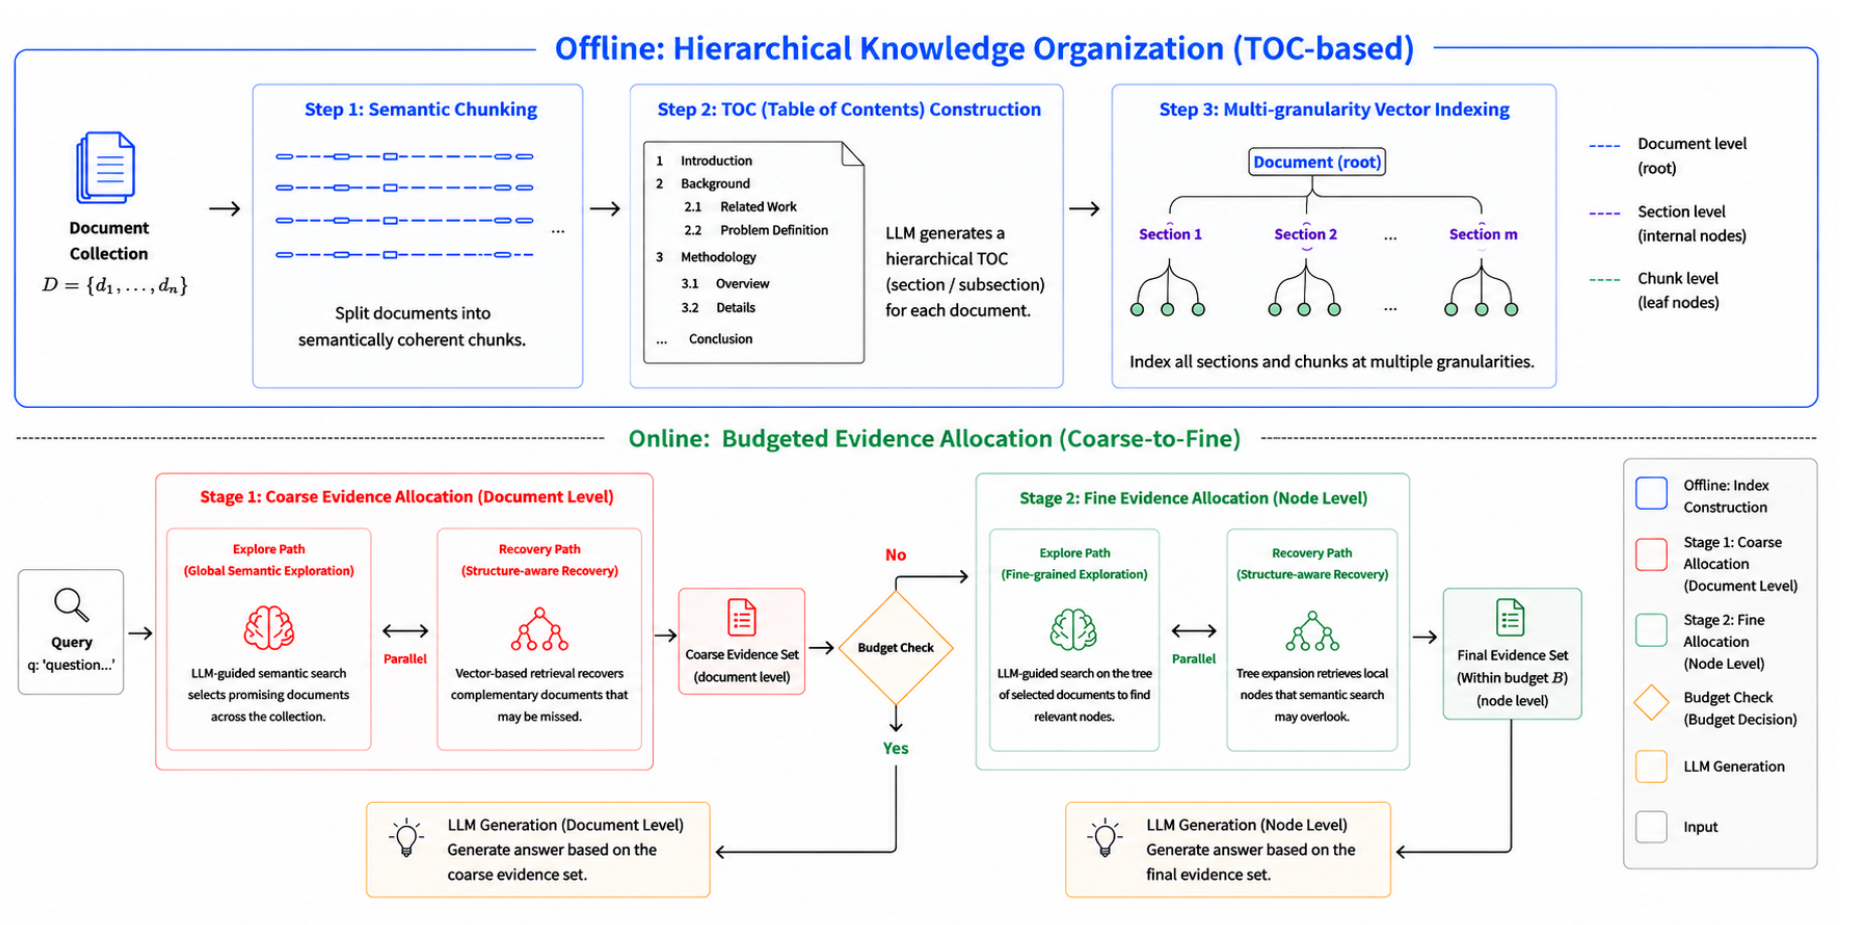
Retrieval and OCR quality alone do not guarantee reliable answers. How can systems allocate evidence across documents and account for document noise?
Document understanding, retrieval, and trustworthy generation, from industrial OCR robustness to budgeted multi-document evidence allocation.
Retrieval and OCR quality alone do not guarantee reliable answers. How can systems allocate evidence across documents and account for document noise?
Combining retrieval, document structure, evidence allocation, and generation evaluation. Related papers cover OCR robustness for RAG, budgeted multi-document evidence allocation, and visual-document RAG.
InduOCRBench spans 12 industries, 570 documents, 3,402 pages, and 11 challenge types. BEAR evaluates hierarchical retrieval and multi-document reasoning under a shared generator and evidence budget.
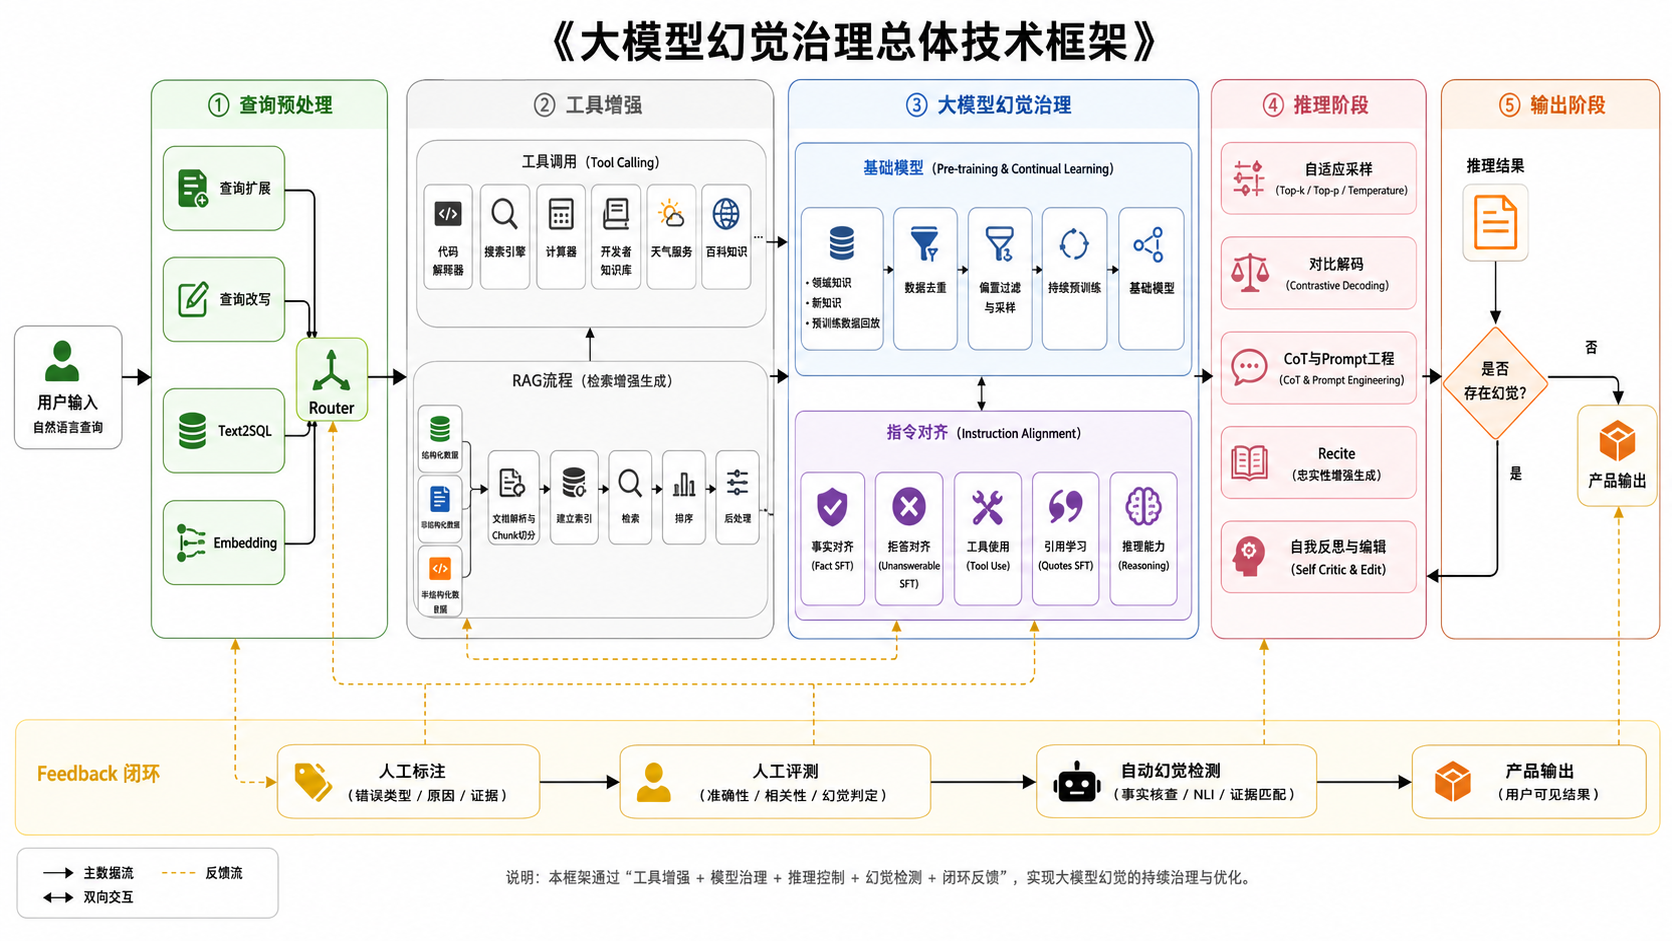
Visual-style documents reach 82.9% OCR accuracy but 52.8% RAG answer accuracy, a 30.1-point gap. Table 2 compares the Avg scores of ten methods on general and industrial-document benchmarks.
| OCR method | OmniDocBench Avg ↑ | InduOCRBench Avg ↑ |
|---|---|---|
| PP-StructureV3 | 86.7 | 60.3 |
| MinerU2 | 75.5 | 66.5 |
| Doc2x | 84.6 | 61.6 |
| GPT-4o | 75.0 | 52.0 |
| Qwen3-VL-235B | 89.2 | 70.9 |
| Gemini-2.5 Pro | 88.0 | 74.5 |
| Deepseek-OCR | 87.0 | 61.5 |
| Hunyuan-OCR | 94.1 | 68.1 |
| MinerU2.5 | 90.7 | 72.5 |
| PaddleOCR-VL | 92.9 | 78.2 |
When Good OCR Is Not Enough · Table 2 / Figure 2 ↗
DragonBall retrieval comparisons use a Qwen3-32B generator, with evidence contexts aligned to approximately 4K tokens where applicable; LongRefiner uses a different auxiliary model. Values are mean ± standard deviation over three runs. BEAR(docs) achieves 34.63 ± 2.17 EM and 48.02 ± 1.45 F1 on 2Wiki.
| Method | Recall % ↑ | Completeness % ↑ | Hallucination % ↓ | Irrelevance % ↓ |
|---|---|---|---|---|
| BM25 | 29.17 ± 1.06 | 35.13 ± 1.84 | 32.55 ± 2.40 | 32.25 ± 1.95 |
| BGE-M3 | 58.17 ± 1.91 | 59.56 ± 2.45 | 28.81 ± 2.26 | 11.54 ± 1.55 |
| RAPTOR | 31.93 ± 1.66 | 59.78 ± 2.70 | 26.50 ± 2.48 | 13.67 ± 1.29 |
| LongRefiner | 29.24 ± 2.32 | 43.86 ± 1.98 | 34.88 ± 2.25 | 21.26 ± 1.87 |
| HippoRAG2 | 68.80 ± 1.75 | 73.37 ± 2.24 | 19.55 ± 1.84 | 6.93 ± 0.93 |
| BEAR(docs) | 85.55 ± 0.47 | 91.86 ± 1.32 | 5.64 ± 1.02 | 2.40 ± 0.49 |
| BEAR(nodes) | 84.25 ± 0.84 | 88.64 ± 1.52 | 7.60 ± 1.12 | 3.71 ± 0.86 |