Problem
How can compact models retain strong reasoning ability while making the method accessible to other researchers?
Open 32B models spanning branch-merge distillation, safety control, and distribution-aware model merging for reasoning, instruction following, and safety.
How can compact models retain strong reasoning ability while making the method accessible to other researchers?
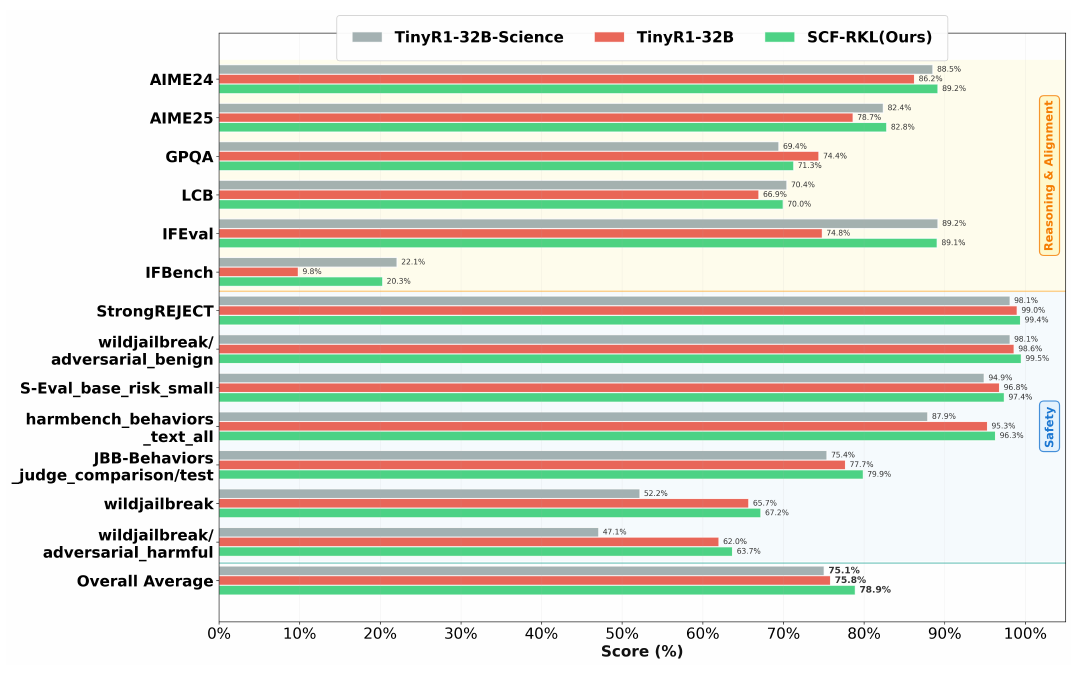
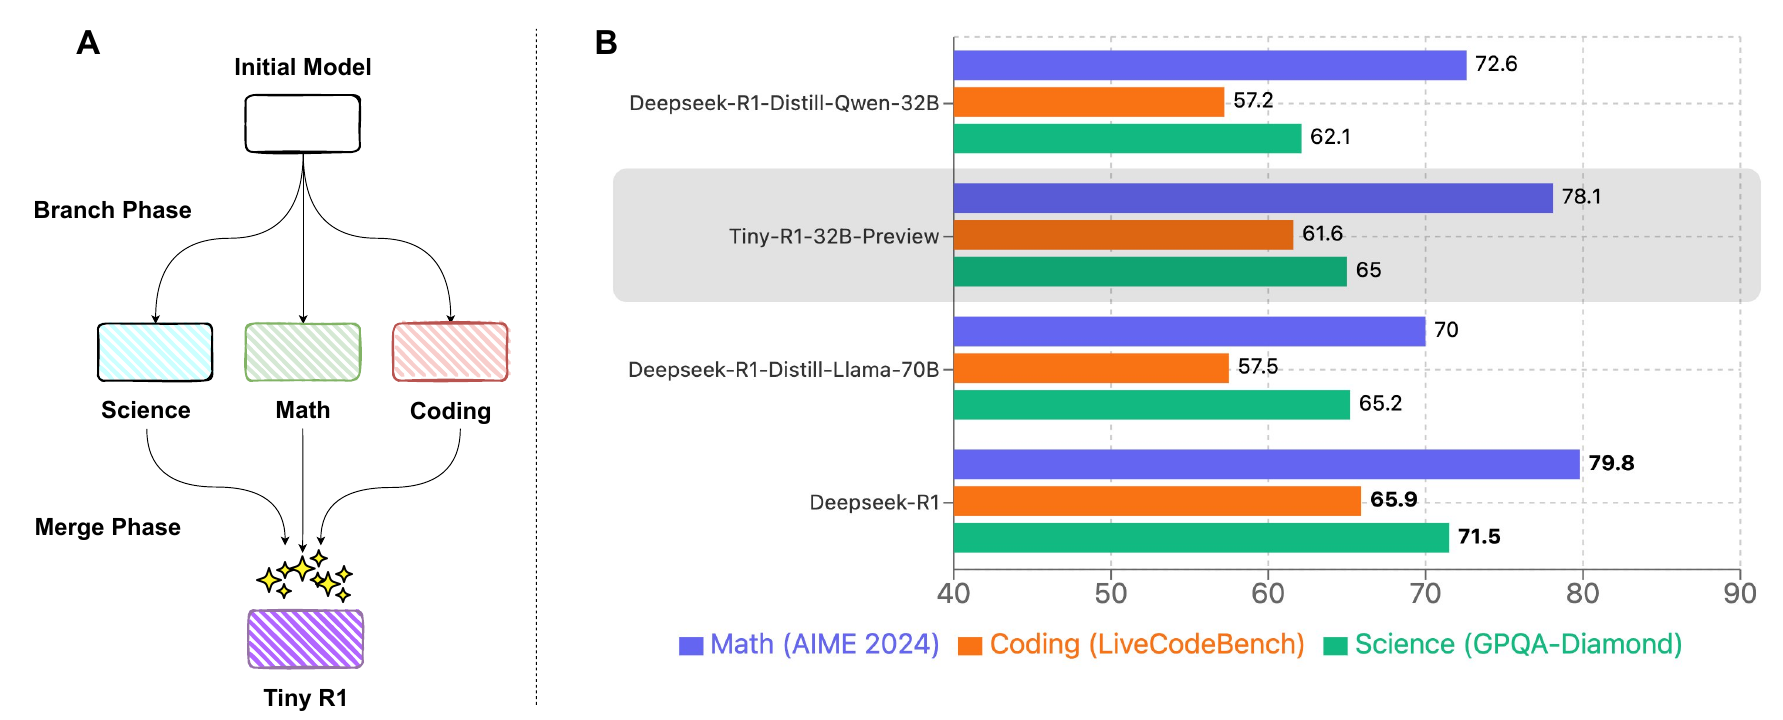
Preview transfers capabilities through math, coding, and science branches followed by merging. TinyR1-32B uses Control Tokens for reasoning and safety; SCF-RKL controls merging interference through sparse complementary updates and reverse KL.
TinyR1 received coverage from the National Natural Science Foundation of China and reached the Hugging Face Trending Top 5. Preview uses 32B parameters, about 5% of DeepSeek-R1’s 671B, with an AIME 2024 score of 78.1 versus 79.8.
Compared with DeepSeek-R1-Distill-Qwen-32B, scores improve by 5.5 points in math, 4.4 in coding, and 2.9 in science. Table 1 reports pass@1; LiveCodeBench uses the 24.08–25.02 subset.
| Model | AIME 2024 ↑ | LiveCodeBench ↑ | GPQA-Diamond ↑ |
|---|---|---|---|
| DeepSeek-R1-Distill-Qwen-32B | 72.6 | 57.2 | 62.1 |
| DeepSeek-R1-Distill-Llama-70B | 70.0 | 57.5 | 65.2 |
| DeepSeek-R1 (671B) | 79.8 | 65.9 | 71.5 |
| TinyR1-32B-Preview | 78.1 | 61.6 | 65.0 |
TinyR1-32B-Preview · Table 1 / Figure 1 ↗
The model card describes three SFT rounds on 20K high-quality samples with Control Tokens for task modes. Results below are from the TinyR1-32B card. Constructive Safety averages HarmBench, JBB-Behaviors, S-Eval_attack, and wildjailbreak.
| Model | Size | AIME24 ↑ | AIME25 ↑ | GPQA-Diamond ↑ | LCB v5 ↑ | IFEval Prompt Strict ↑ | Constructive Safety OpenSource ↑ |
|---|---|---|---|---|---|---|---|
| DeepSeek-R1-0528 | 671B | 91.4 | 87.5 | 81.0 | 73.3 | 80.9 | 73.0 |
| Qwen3-235B-A22B-Thinking-2507 | 235B | — | 92.3 | 81.1 | 74.1 | 87.7 | 65.5 |
| Qwen3-32B | 32B | 81.4 | 72.9 | 68.4 | 65.7 | 85.0 | 64.5 |
| TinyR1-32B | 32B | 90.9 | 82.7 | 69.4 | 70.4 | 89.2 | 89.5 |
SCF-RKL achieves a ten-benchmark average of 65.33 when merging TinyR1-Preview-Math-32B and TinyR1-Preview-Science-32B. Selected individual scores and the original ten-task average are from Table 1. Figure 9 shows a separate experiment merging reasoning- and safety-specialized models.
| Method / model | AIME24 ↑ | GPQA ↑ | LCB ↑ | 10-task average ↑ |
|---|---|---|---|---|
| Math-32B | 74.58 | 67.99 | 61.65 | 64.47 |
| Science-32B | 78.02 | 68.78 | 61.47 | 63.54 |
| Task Arithmetic | 77.50 | 68.18 | 57.80 | 57.90 |
| DARE Task Arithmetic | 77.50 | 68.18 | 55.91 | 57.80 |
| TIES Merging | 74.38 | 67.08 | 50.18 | 55.55 |
| DARE TIES Merging | 76.15 | 67.08 | 56.90 | 58.22 |
| SCE | 74.38 | 67.08 | 49.91 | 55.47 |
| SCF-RKL | 76.98 | 69.19 | 62.46 | 65.33 |
Beyond Parameter Arithmetic · Table 1 / Figure 9 ↗